#context

What is a subagent — and why it saves context, not time
A subagent is a separate agent with a clean memory. It reads forty files and hands you back five lines: all the search noise stays with it, not with you.
What is AGENTS.md — the file your AI agent reads before you ask
AGENTS.md is a plain Markdown file in your project root. AI coding agents read it on their own before they start. Here's what belongs in it — and what stays in the README.
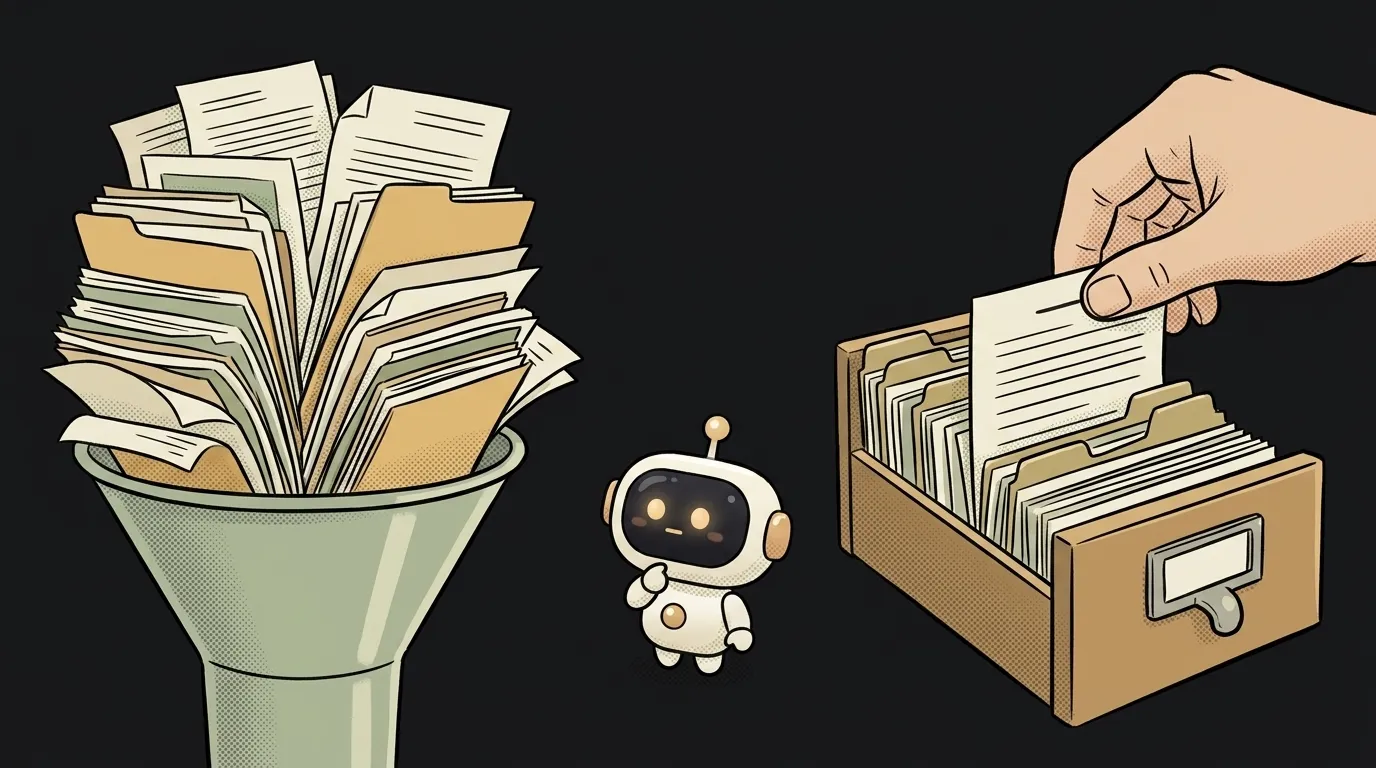
RAG or long context — paste your documents in or search through them
Context windows grew to a million tokens — so is RAG obsolete? Not so fast. We compare RAG and long context on cost, freshness, and reliability.
How to give AI context about your code — so it stops guessing
AI writes off-target because it can't see your project. Here's a step-by-step way to give AI context about your code with a single file — so answers get accurate.
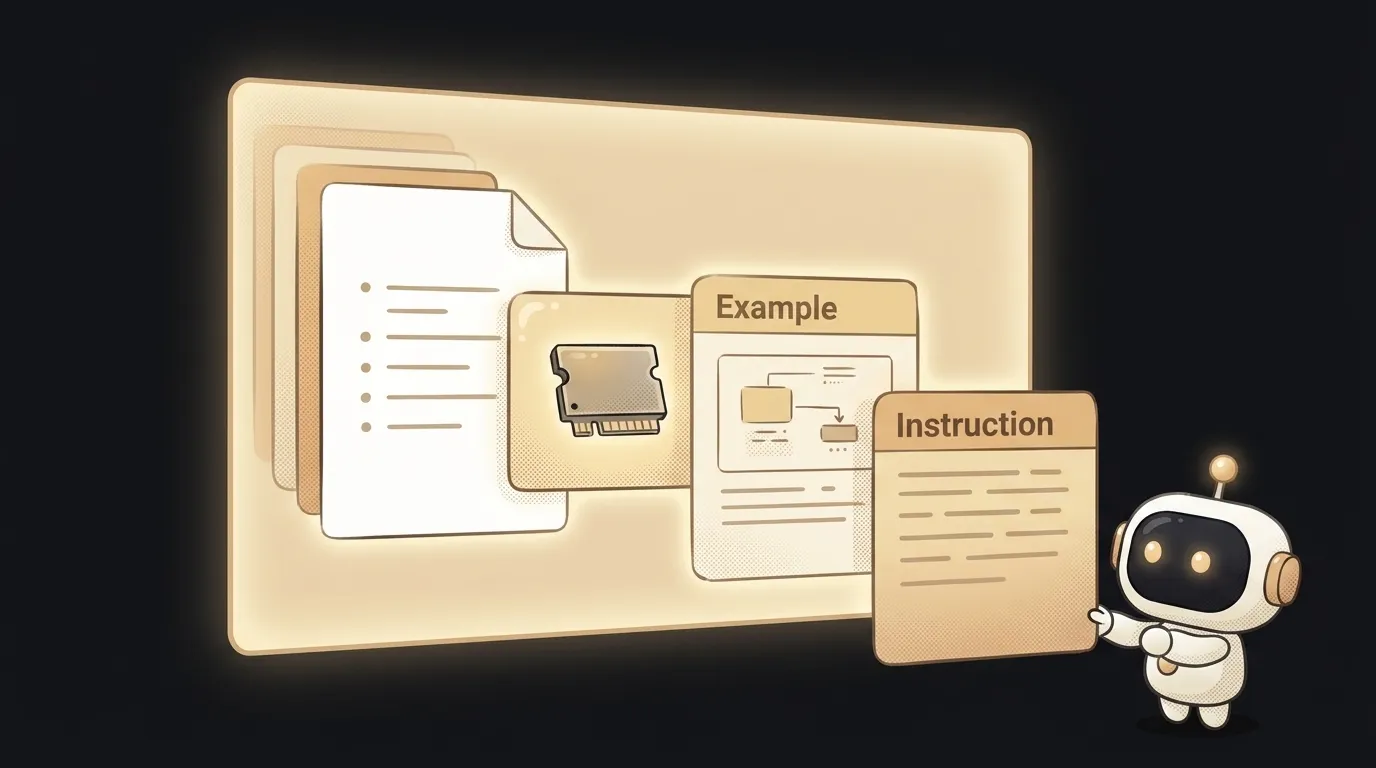
What is context engineering — and why it beats the prompt
A prompt is how you phrase one line. Context engineering is what the model sees as a whole when it answers. The second matters more. Here's why.
Why your bot forgets what you talked about — and how to fix it
Bot loses the thread and re-asks what you already said? Usually it's not a glitch. Three real reasons AI forgets context, and what to do about each.
What is AI memory — and why the model forgets what you said a minute ago
What memory means for an AI assistant: why the model doesn't 'remember' but re-reads the chat from scratch, how chat memory differs from persistent memory, and how to use each.

Drop a year of chats into one prompt — and ask anything
This used to need a vector database and RAG. Now a whole year of chats fits in one prompt — million-token context just got far cheaper.
Drop a whole book into a model — and ask without chunk-searching
Big files used to get sliced up and searched (that's RAG). GLM-5.2 just shipped — a million tokens of context, open and cheap. Now the whole document fits in one request. Starter prompt included.
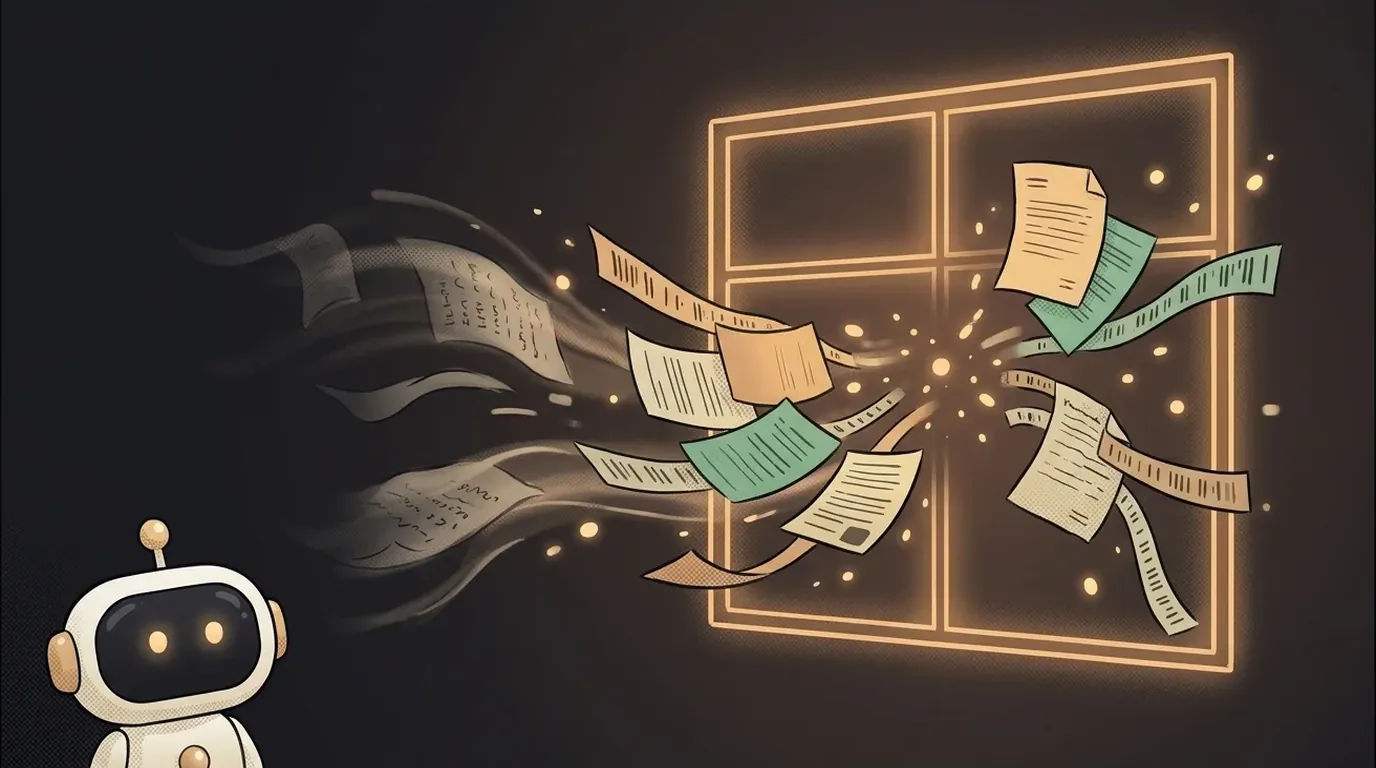
What is a context window — and why AI forgets the start of a conversation
In a long chat, old messages get pushed out of the model's memory — that's why it loses the thread. Explained with a simple picture.