What is a Bloom filter — the data structure that lies, but only one way
Here's a strange thing. There's a data structure that sometimes gets it wrong — and serious databases use it anyway. On purpose.
The secret is how it's wrong. A Bloom filter can say "maybe it's there" when the item isn't. But if it says "definitely not" — that's always true. And for this one-sided lie it charges about 10 bits per item. Not 10 bytes — 10 bits.
What a Bloom filter is, simply
A Bloom filter answers one question: "have I seen this item before?" There are two answers:
- "Definitely not" — guaranteed.
- "Maybe yes" — double-check in the real storage.
The filter doesn't store the item itself. Only a fingerprint of a few bits. That's why it's tiny — and why it can never say "definitely yes".
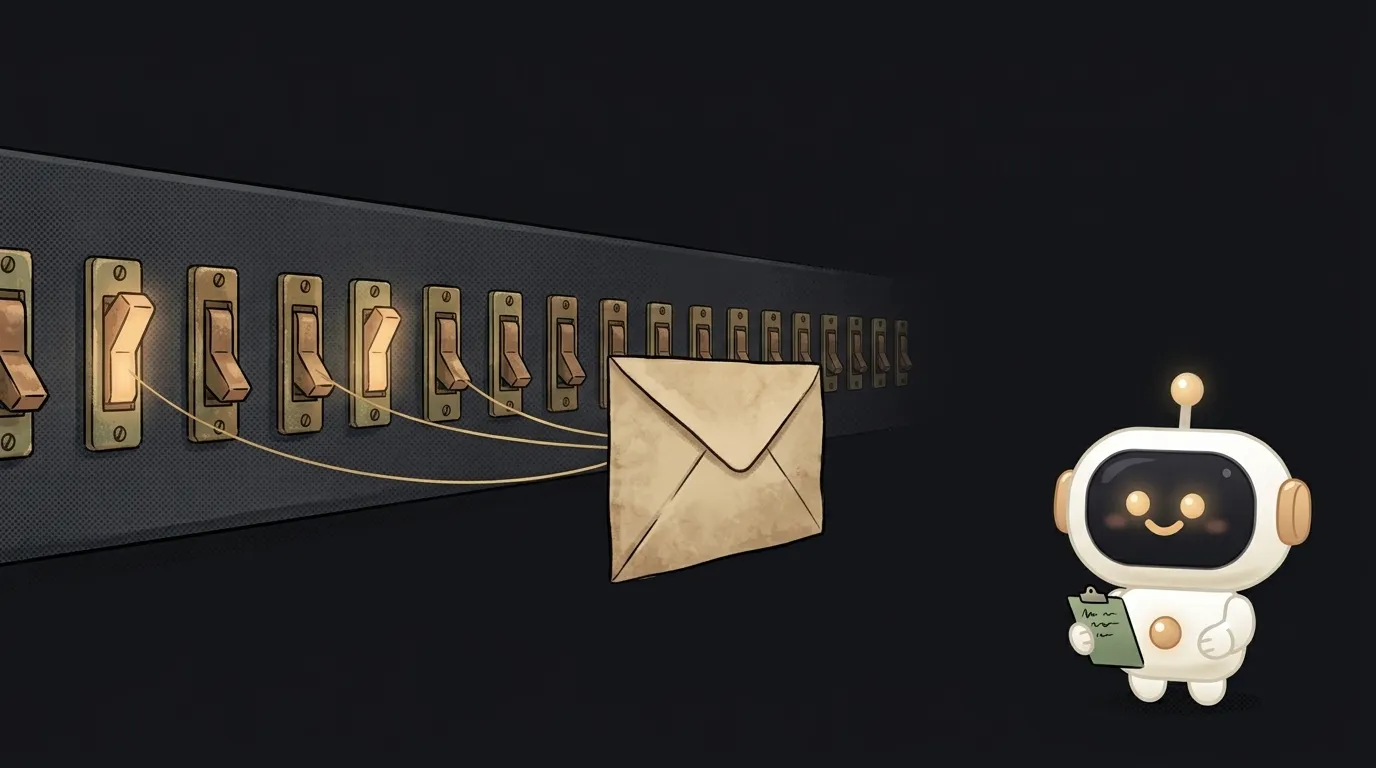
Picture a wall with a row of switches, all off. Each letter maps to three switches — a formula picks them from the address. A letter arrives — you flip its three switches up. Want to know if a letter came? Look at its three switches. Even one is down — the letter never came, for sure. All three up — it probably came. Or maybe three other letters each flipped one of them.
How it works
Inside, there's an array of bits and a few hash functions. A hash turns a string into a number — the bit's position.
- Add
"cat": the three hashes give, say, 2, 7 and 11. Set those three bits to 1. - Add
"dog": the hashes give 4, 7 and 13. Bit 7 is already set — no problem. - Check
"tree": the hashes give 2, 9 and 13. Bit 9 is zero. So "tree" was definitely never added. - Check
"yard": the hashes give 2, 4 and 11. All three are ones. The filter says "maybe". But nobody added "yard"! "cat" and "dog" lit those bits. That's a false positive.
The bigger the array per item, the rarer those collisions. The classic number: about 9.6 bits per item give 1% false "yes" answers. And it doesn't depend on how long the items are. Short usernames or long URLs, same cost.
For scale: a billion items at 1% error is roughly 1.2 GB. The strings themselves would take many times more.
Why it matters to you
The filter sits in front of an expensive check and skips work that's obviously pointless.
- "Is this username free?" The user types a name and you want live hints. The filter says "definitely not" — the name is free, no trip to the database. It says "maybe" — check the database. Most candidates get filtered out without a query.
- "Have we shown this already?" A feed shouldn't show the same article twice. A per-user filter remembers thousands of viewed items in a couple of kilobytes.
- "Is it in the cache?" Before a slow trip to disk or the network. It's a cousin of caching: instead of storing the answer, you know where it definitely isn't.
Three rules worth remembering:
- Errors only go toward "maybe yes". If that's exactly the error you can't afford — a filter isn't for you.
- You can't delete an item from a plain filter. Clearing its bits would hit its neighbours. For deletion there's a variant with counters instead of bits.
- Size it up front. An overfull filter, where almost every bit is 1, answers "maybe" to everything and becomes useless.
Where you'll meet it
- Cassandra, HBase and other LSM-tree databases. Every data file on disk has its own filter. Looking up a key, the database asks the filters first and skips the files where the key is "definitely not". In Cassandra, the error rate is a table setting:
bloom_filter_fp_chance. - Postgres. There's a
bloomextension — an index built on a Bloom filter for queries over many columns at once. - Blocklists. A quick local check that "this address is definitely not on the dangerous list" before asking a server.
- Redis — via a module with
BF.ADDandBF.EXISTScommands.
How is a Bloom filter different from a Set?
A Set stores the items themselves and answers exactly, but it grows with the data. A filter stores only bits and takes a fixed amount of space, but it can err toward "yes". As long as the data fits in memory — use a Set.
Can I get the list of items back out of a filter?
No. You can't reconstruct what was added from the bits. That's both a limitation and a plus: the filter doesn't reveal the data itself.
How many hash functions do I need?
For 1% errors, about seven is optimal. More hashes means each item lights more bits, and the array fills up faster. Ready-made libraries compute the number for you from the error rate you want.
Short story-lessons, an agent simulator and daily practice — in our mobile app. Free.
Read next
What is an LRU cache — and why a cache with no limit becomes a memory leak
What is a sliding window — the trick that finds your 'best week' in one pass
encodeURI vs encodeURIComponent — the difference, and why 'Tom & Jerry' searches for 'Tom'
What is a ring buffer — and why old logs vanish on their own
What is a heartbeat — and why an "open" connection can be long dead