What is an LLM router — and why you shouldn't pick one model forever
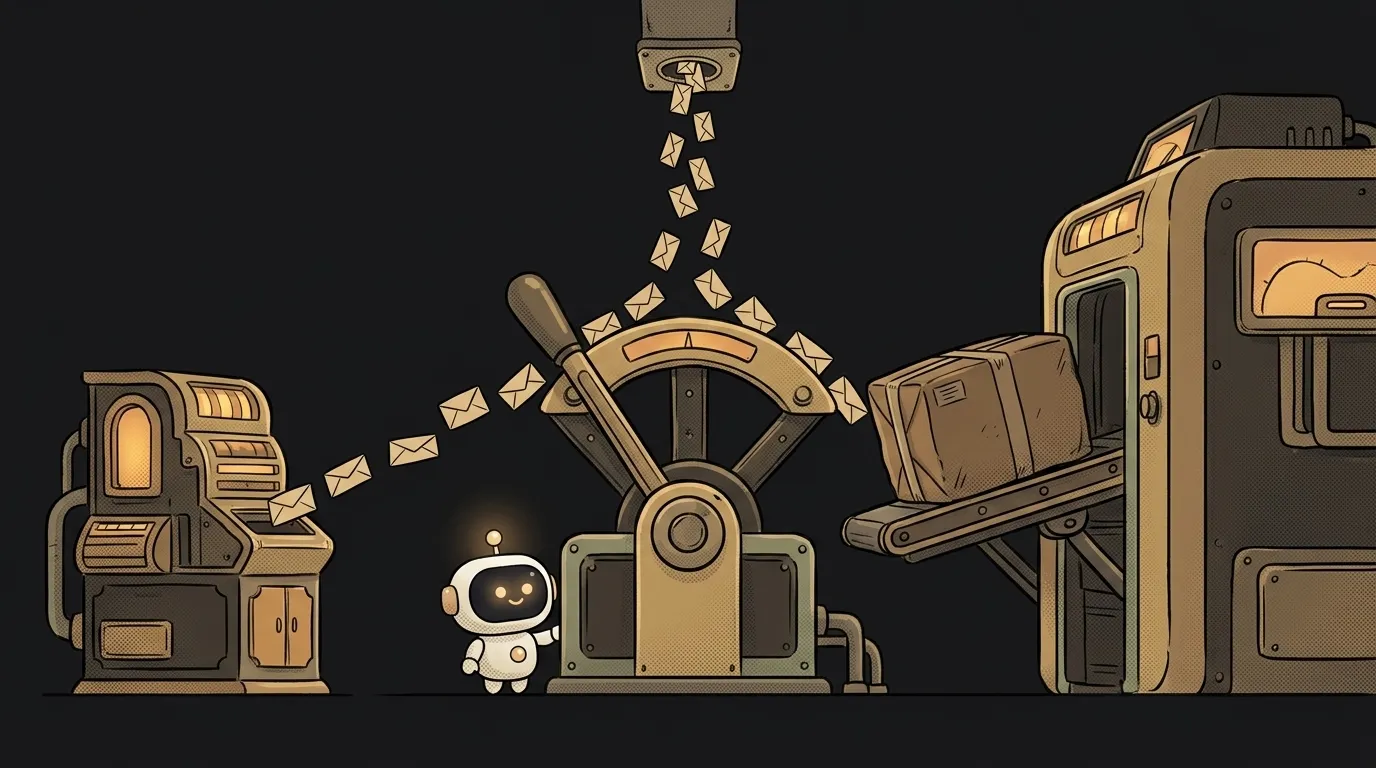
Look into your AI app's logs one day and you'll be mildly depressed.
You'll find "hi", "thanks", "make it shorter", "in English please". And somewhere between them, three real requests — the ones the whole thing was built for.
The problem: you pay the same price for "thanks" as for real work. There's one model wired into the whole app. That's where the idea of a router comes from.
What an LLM router is
An LLM router is a layer that picks the model per request, instead of once when you wrote the code.
Here's how apps usually work: a model name is hardcoded, and every request — from "hi" to "review my contract" — goes there. It's like calling a truck to deliver a letter. Sometimes the cargo really is big. Most of the time it isn't.
A router inserts one fork between the user and the model: look at the request → decide who can handle it → send it there.
Simple questions go to a small, fast model. Hard ones go to the flagship. The user sees no difference — the answer arrives in the same shape, some answers just cost you pennies.
Why it cuts the bill more than you'd expect
This isn't "the cheap model is worse but we'll live with it." It's about the shape of your traffic.
In any live product the request mix is lopsided: most of the volume is short, banal, repetitive stuff. Greetings, follow-ups, "show that again", taps on the "make it shorter" button. Actual hard work is a couple of percent.
Meanwhile the price gap between a small and a flagship model from the same provider is usually tens of times. Not percent. Tens of times.
Multiply the two and you get something unpleasant: most of your bill goes to requests that needed no intelligence at all. A router hits exactly that slice — without degrading the hard answers, because it never touches them.
That's the most underrated item in any conversation about cutting your AI costs: people start by trimming prompts word by word while a much bigger lever sits right there.
Your first router is an if, not an AI
The word "router" sounds serious, as if you need a separate smart dispatcher model. You don't. Start with rules — they're free and instant.
function pickModel(text, hasFiles) {
  if (hasFiles || text.length > 2000) return "flagship"   // long text, documents
  if (/calculate|code|error|why/i.test(text)) return "flagship"
  return "small"                                          // everything else
}
Five lines. No magic, and you immediately see in the logs what share of traffic moved down.
From there it's worth escalating in steps:
- Rules — length, attached file, keywords. Zero latency, zero cost.
- Cascade — small model first, retry on the flagship only if its answer fails a check. You pay twice, but rarely.
- A classifier model — a tiny model decides "simple or hard". Worth it once rules stop catching the cases.
Most projects never need past step one. This is one of those times where the naive fix honestly captures nearly all the win.
Ready-made routers, if you'd rather not build one
You don't have to hand-build the fork. There's OpenRouter — a broker whose openrouter/auto model makes the pick for you.
The mechanics are interesting: the request gets classified, then it goes to whichever model the OpenRouter community is actually spending money on in that category over the past week. So the router follows a live vote with wallets rather than benchmarks. There's a cost_quality_tradeoff dial from 0 to 10 (default 7): 0 reaches for the most capable model, 10 for the cheapest. There's no surcharge for the router itself — you pay the selected model's normal rate, and the model field in the response tells you which one ran.
One more nice detail: within a single conversation the router pins the chosen model, so answers don't visually jump in style from turn to turn.
What it costs you
Honestly, three downsides.
- Less predictable answers. The same question can land on different models on different days, and the tone drifts. Fix: pin the model inside a conversation.
- Misses at the boundary. A request that looked simple but wasn't gets a weak answer. So bias your router upward: a wrong "up" costs cents, a wrong "down" costs user trust.
- One more thing that can break. The router is code standing in front of every request. Keep a fallback: can't decide → send it to the flagship.
And one upside people notice later: once model choice lives in a single function, switching models is a one-line edit instead of a search across the whole project.
Is a router a separate service or a library?
Neither, by default. In its simplest form it's your own few-line function inside your own code. A separate service starts to make sense when you have many models across several providers and want shared stats — at that point a ready-made gateway like OpenRouter beats maintaining your own.
How do I know the router actually helped?
Log two things per request: which model the router picked, and how many tokens it burned. A day later you'll have the share of traffic that went to the cheap model — that's your saving, in the clear. You'll also spot the requests it routed wrong: they usually cluster around one phrasing, and the rule is fixed with one line.
The AI Architect 2027 course: step by step from computer basics to your own app and first customers. 543 short lessons on your phone.
Read next
Claude Code or Codex — and why price is the worst way to choose
Minification or compression — the difference, and why you need both
Word blocklist vs AI moderation — what to filter user content with
WebAssembly vs JavaScript — what's actually faster, and when
Accessibility overlay or real fixes — what to choose for your site