What is exponential backoff — and why it fails without randomness
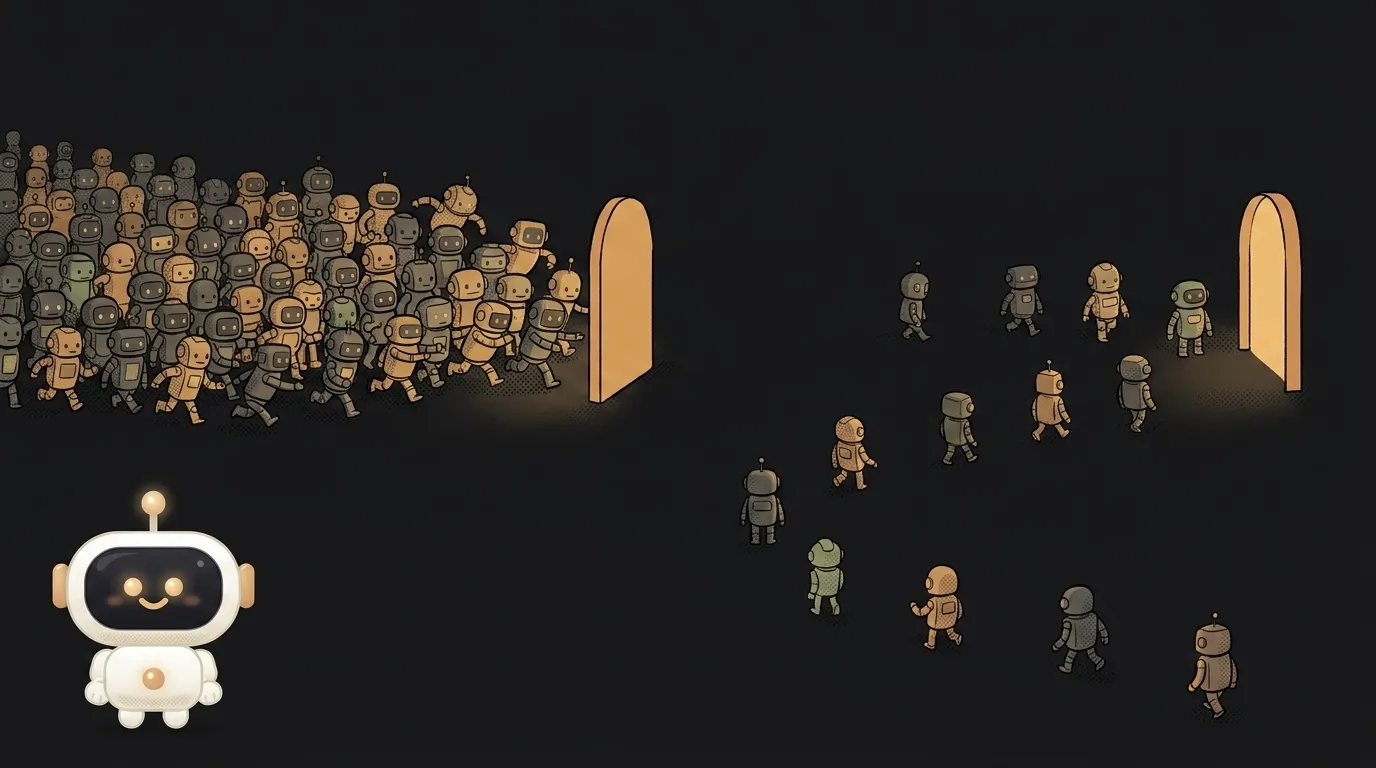
Here's an annoying one. A service answered "too many requests". You did it by the book: waited a second, then two, then four.
And still finished it off.
Because a hundred other clients did exactly the same. You all waited identically — and came back as one wave.
What exponential backoff is
It's a rule for the pauses between retries: each pause is twice as long as the last one.
- first retry — after 1 second
- second — after 2
- then 4, 8, 16…
Why. A service that's choking needs time. Retrying after 50 milliseconds pours load exactly where there's already too much of it. The exponent gives it a breather that grows on its own until the problem clears.
So far so good. The trouble hides in the word "identically".
Why doubling alone isn't enough
A service has more than one client. When it's down, everyone gets the error at once — and everyone starts the same stopwatch.
A second later, a wave hits. The service chokes again. Two seconds later, another wave of exactly the same shape. It never recovers, it just gets punched less often.
AWS engineers measured this: with plain exponential backoff "there are still clusters of calls" on the graph, and contention barely drops. Silence, then a volley.
Jitter — the randomness that makes it work
Jitter is a random component added to the pause. Instead of "wait exactly 4 seconds" — "wait a random time between zero and four".
The formula worth memorising (it's called full jitter):
sleep = random(0, min(cap, base * 2 ** attempt))
Look at what changed. The wave smears out: one client comes back after 0.3 seconds, another after 3.8. The service gets a steady trickle instead of a battering ram — and gets a chance to dig out.
In that same AWS measurement, full jitter cut the number of calls by more than half compared to backoff without randomness. One line of code.
What to retry, and what's pointless
Backoff only helps with temporary failures. The test is simple: will anything be different if you wait?
Worth retrying:
- 429 — the rate limit is used up, the window resets in a minute
- 500, 502, 503, 504 — server, gateway, overload
- dropped connections and timeouts — there was no answer at all
Pointless to retry:
- 400 — you sent broken JSON; it won't straighten out in an hour
- 401 and 403 — wrong key or no permission (a classic)
- 404 — the object isn't there
- 422 — the data failed validation
Retrying a 401 isn't resilience. It's a free attack on yourself.
When the server tells you how long to wait
Sometimes the response carries a Retry-After header — most often with 429 and 503. Inside is either a number of seconds (Retry-After: 120) or a date.
The rule: if it's there, obey it, and use your own formula only when it isn't. But don't treat it as a guarantee. MDN warns outright that support for Retry-After is still inconsistent — half the services simply don't send it.
What this has to do with AI
Quite a lot. Model APIs enforce hard limits, and an agent calls tools on its own, without you. A naive "didn't work — try again" loop looks like this: twenty requests a second, your whole daily quota gone in a minute, and a bill you'll see tomorrow.
Backoff with a cap and a maximum number of attempts is what separates a working agent from a despair loop.
Next up, the practice: how to retry failed requests properly, step by step and with an idempotency key.
The three most common mistakes
Retries inside retries. The sneakiest one. Your HTTP client library already does 3 attempts, you wrapped your own logic for 5 on top — that's 15 requests instead of 5, each layer with its own cap. Check the client's settings before writing your own loop: retries are often on by default.
Retrying with no cap. 2 ** 10 is about 17 minutes. The user left long ago, and your process is still waiting.
No limit on total time. Five attempts at 20 seconds each is a minute and a half during which the request holds a connection and memory. Bound the total time budget, not just the number of attempts.
How many times should I retry?
For a background job — three to five attempts. For a request with a live person waiting — one or two, then an honest error: a user would rather see "try again" than a spinner for a full minute. Always cap the pause, usually at 20–60 seconds.
Is backoff the same as a timeout?
No, and confusing them is expensive. A timeout says how long to wait for one answer. Backoff says how long to wait between attempts. Without a timeout the retry may never even happen: the request hangs forever waiting for an answer that isn't coming.
Won't jitter make responses slower?
On average it's the opposite. A random pause is sometimes shorter than a fixed one — and more importantly, the service stops falling over from your own retries. The fastest service is the one you don't keep hitting.
The AI Architect 2027 course: step by step from computer basics to your own app and first customers. 543 short lessons on your phone.
Read next

Ed25519 vs RSA — which SSH key to choose in 2026

What is sudo — and why it asks for your password, not the admin's

What is a tar.gz file — and why a tar archive can be bigger than the files

What is a command-line flag — and why git commit -ma breaks but -am works

scp or rsync — and why rsync sent 141 bytes instead of two megabytes the second time
