What is a reranker — and why semantic search finds the exact opposite
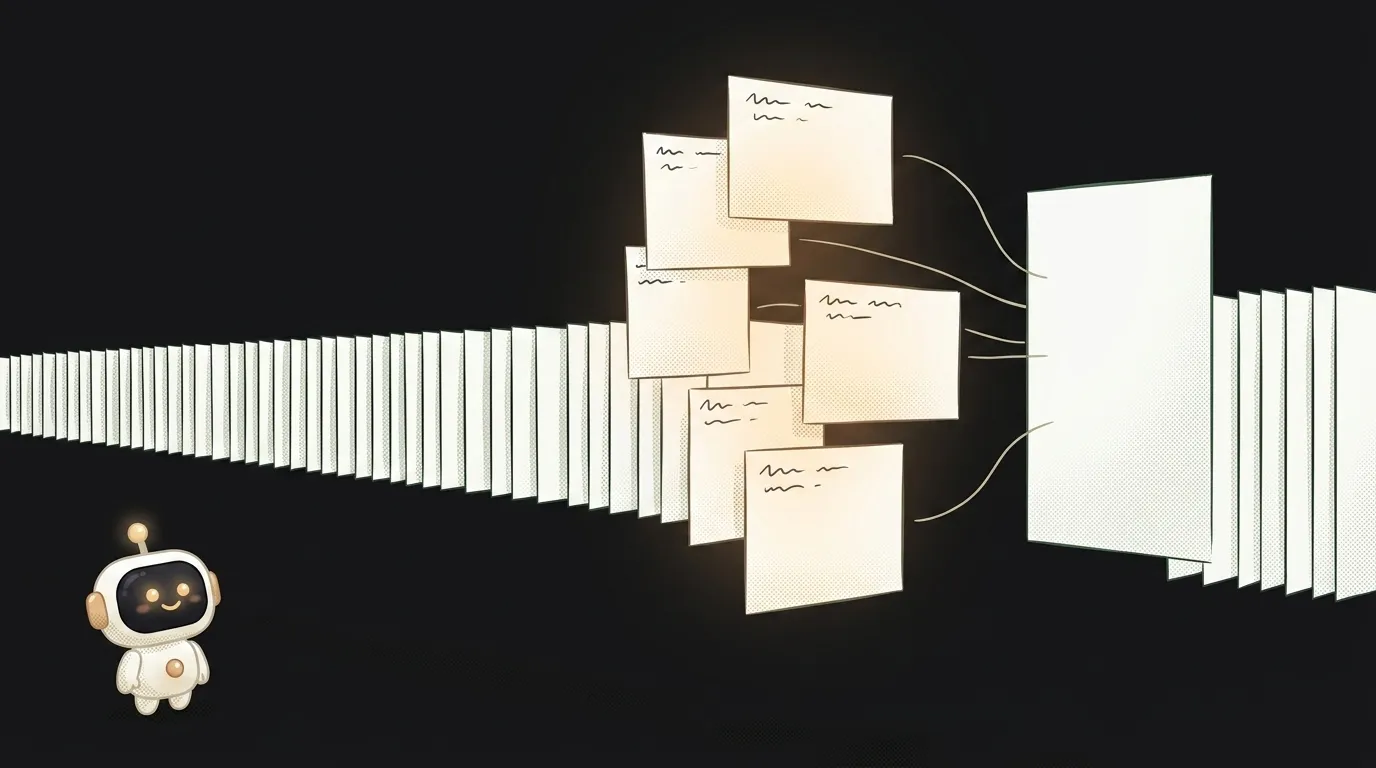
Here's an annoying one. You built a bot over your own docs. You ask: "does payment by card work?" The bot answers confidently: "Yes, it works." Your docs say the opposite, in plain text.
You check the database — the paragraph is right there. Search just didn't pull it. Or it did, third from the bottom.
The model isn't the problem. The problem is that semantic search never compares texts at all.
Vector search compares two summaries
When you load documents into a vector database, every chunk is turned into an embedding ahead of time — a short numeric summary. The user's question becomes the same kind of summary at query time.
From then on, only the summaries are compared. The text and the question never actually meet.
That's where the speed comes from. Documents are precomputed, so you can scan a million chunks in tens of milliseconds. This is how any semantic search works.
And that's also where the misses come from. A summary is lossy compression. What gets lost first is exactly the stuff that weighs little in characters but flips the meaning:
- "card payments work" and "card payments do not work" — nearly identical vectors;
- "good for large files, except video" — the "except video" blurs away;
- "we used to support X" — the past tense disappears.
Negation is one word. In a summary of 1536 numbers it barely leaves a trace. So vector search is great at finding similar, but guarantees nothing about correct.
A reranker reads the question and the text together
A reranker works differently. It takes a pair — question plus one chunk — glues them into a single input and runs the whole thing through a model. Every word of the question attends to every word of the document.
That kind of model is called a cross-encoder, as opposed to a bi-encoder that encodes both sides separately. The output isn't a distance between summaries but a single number: how well this text answers this question.
This is where negation surfaces. The model sees "not" next to "work" and drops the score.
The cost is direct: nothing can be precomputed. The question is new every time, so the model runs fresh for every pair. Measured latency between an embedding pass and a cross-encoder pass differs by 4x to 57x — roughly 23–330 ms per pair on CPU.
Multiply that by a million chunks and you get hours. That's why a reranker can't search your whole database. It only ever works second.
The pattern that works: fetch 50, keep 5
The working pipeline in RAG looks like this:
- Vector search pulls with headroom — not top-5 but top-50. Cheap and fast.
- The reranker rescores those 50 honestly, in pairs.
- The top-5 after rescoring go into the prompt.
Step 1 is the critical one. The first stage is responsible for the right chunk making it into the fifty candidates at all. The second is responsible for lifting it to the top.
Which gives you an important rule: if the right text isn't in the top-50, the reranker can't save you. It doesn't search, it re-sorts.
How much does it help? In Anthropic's contextual retrieval research, contextual embeddings plus keyword search cut failed retrievals by 49%, and together with reranking by 67%. Two thirds of the misses gone.
And the question everyone asks: "why not just take all 50 and stuff them into the prompt?" Bad idea. Models handle the middle of a long context window worse — the paragraph that lands mid-wall is read less carefully than the first one. Plus you pay for all 50 chunks in tokens on every single request.
When you don't need a reranker
Don't add one reflexively. Three cases where it's dead weight:
- Small knowledge base. If all your docs fit in the model's context, don't build search at all — hand over the whole text.
- Simple keyword-ish queries. "Return policy" gets found without any re-sorting.
- Latency matters. A voice assistant that must answer within a second will feel the extra 300 ms.
There's one honest way to check. Collect 20–30 real questions, write down which chunk was the correct answer for each, and look at two numbers: how often the correct chunk landed in the top-5 without the reranker, and with it. No difference means you just bought yourself latency.
Is a reranker a separate model?
Yes, separate and small. There are hosted APIs (Cohere Rerank, Voyage) and open models like bge-reranker-v2-m3 you can run locally. You don't need a generative model for this, and using one is overkill.
Can better embeddings replace it?
Partly. Good chunking and adding context to each chunk buys you more than swapping embedding models. But a summary loses negation with any model — that's a property of the approach, not of quality.
How many candidates should the first stage return?
Start with 50 and measure. More candidates means a higher chance the right one is inside, but slower rescoring. Below 20 is usually pointless: the reranker has nothing to re-sort.
The natural next step is figuring out how to cut documents into chunks — that decides whether a chunk worth lifting exists in your database at all. That's the guide on chunking documents for RAG.
The AI Architect 2027 course: step by step from computer basics to your own app and first customers. 543 short lessons on your phone.
Read next

What is headless mode for an AI agent — and why it silently skips steps

What is a hook in an AI agent — the rule the model can't ignore

What is a slash command in an AI agent — and why it's just a saved prompt

What is an Agent Skill — and why it costs almost nothing

What is a subagent — and why it saves context, not time
