What is cosine similarity — and why 0.8 doesn't mean "80% match"
You've built semantic search, and it returns results with scores: 0.86, 0.81, 0.79. You set the threshold at 0.5 — "that's half, right?" — and garbage floods the results.
Here's the thing: 0.8 does not mean "80% match." These aren't percentages at all. And that misunderstanding is exactly why thresholds get picked at random and then surprise people with junk. Let's work out what the number actually is.
Cosine measures direction, not distance
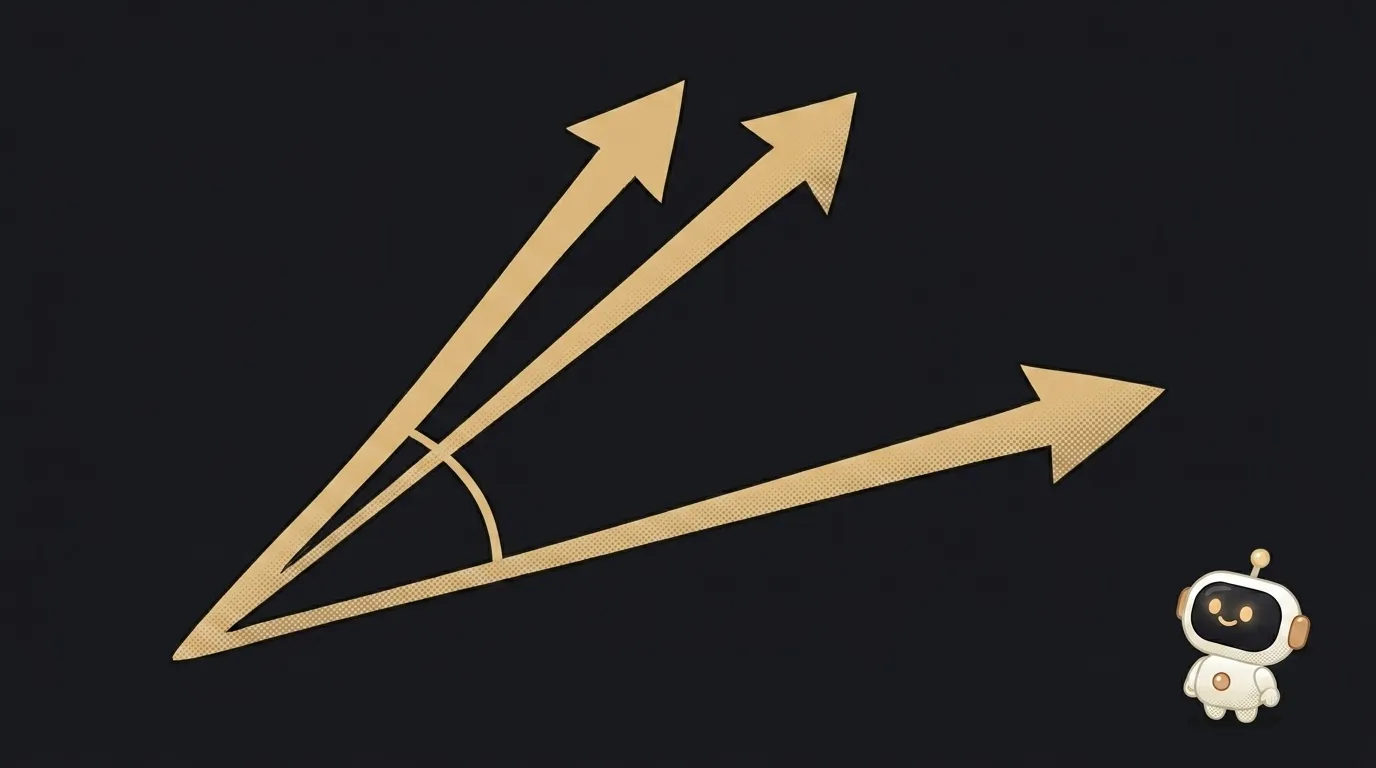
An embedding turns any text into a long list of numbers — a vector. Geometrically that's an arrow pointing out from the origin in some direction.
An arrow has two properties: where it points and how long it is. Cosine similarity only looks at the first. It measures the angle between two arrows and completely ignores their length.
Why that matters shows up in an example. Take a short note, "how to brew tea," and a detailed three-page article about the same thing. The second is longer, its vector is "bigger." If you measure plain distance between arrow tips, the long text lands far from the short one — purely because it's long. Same meaning, but the metric says "not similar."
Cosine doesn't fall for it. Both arrows point roughly the same way — small angle — so the texts are about the same thing. That's exactly why it became the standard for semantic search.
The scale: 1 means the arrows point the same way, 0 means a right angle and no relationship, −1 means opposite directions.
Why you often don't need to choose a metric at all
Now for the surprising bit that saves a lot of arguing.
The cosine formula is the dot product of two vectors divided by their lengths. And nearly every embedding provider hands back vectors that are already normalized — scaled to a length of exactly 1.
Dividing by one does nothing. So for normalized vectors, cosine similarity is literally equal to the dot product.
OpenAI says so directly in its docs: their embeddings are normalized to length 1, so cosine similarity can be computed faster as a dot product with the same result. More than that — the ranking will be identical to Euclidean distance too.
The practical takeaway: if your vectors are normalized, the "cosine vs dot product vs Euclidean" debate is empty. The ranking comes out the same; only the compute speed differs. Pick whichever is fastest in your vector database and move on.
So what do the numbers mean?
Here you have to accept an uncomfortable truth: the absolute cosine value on its own means almost nothing.
The reason is that text-embedding vectors aren't spread evenly through the space. They cluster. Two random, entirely unrelated texts in the same language still share something — grammar, register, the sheer fact of being text — and their cosine will sit noticeably above zero rather than near it.
How far above depends on the specific embedding model. So 0.5 in one model can mean "totally unrelated" while in another it means "perfectly relevant."
Worse: the distributions of similar and dissimilar pairs overlap. OpenAI's cookbook shows this plainly — the charts make clear that some dissimilar pairs score higher than some similar ones. A perfect threshold that separates them cleanly simply doesn't exist.
How to set a threshold like a grown-up
Don't guess — measure. The procedure:
- Collect 20–30 real queries — ones actual users type, not invented ones.
- Run the search and look at the full result list — scores included, no cutoff.
- Mark by eye where useful ends and junk begins. You'll get a band — say "relevant above 0.74, irrelevant below 0.71."
- Set the threshold at the bottom of the useful band and re-check against fresh queries.
And keep the alternative in mind: it's often more robust to take a fixed top 5 rather than "everything above X," and hand those to the model. Then the numbers don't matter at all — only the ordering does. For RAG that's usually the right mode.
Why is cosine negative in theory but never in practice?
Mathematically the scale runs from −1 to 1, and −1 would mean "opposite meaning." With text embeddings you almost never see it: the model encodes topic, not stance. "I love coffee" and "I hate coffee" land very close together — they're both about coffee.
Do I need to normalize vectors myself?
If a hosted API produces them, usually no — they're already normalized. If you trained the model yourself or pulled one from Hugging Face, check: compute the length of a couple of vectors, and if it isn't about 1, normalize before comparing. Otherwise the dot product stops matching cosine, and long texts start winning on length alone.
The AI Architect 2027 course: step by step from computer basics to your own app and first customers. 543 short lessons on your phone.
Read next

Ed25519 vs RSA — which SSH key to choose in 2026

What is sudo — and why it asks for your password, not the admin's

What is a tar.gz file — and why a tar archive can be bigger than the files

What is a command-line flag — and why git commit -ma breaks but -am works

scp or rsync — and why rsync sent 141 bytes instead of two megabytes the second time
